A new research paper from the COIL-D initiative.

COILD: An Indic-Centric Parallel Corpus and Benchmark for Machine Translation Across Indian Languages

Read Paper →
We are Hiring!

Currently we hiring for different positions.

We are hiring for JRA (Language ODIA) under the COIL-D initiative at IIT Patna.

To apply →
News Update

IIT-Patna’s AI Initiative Set to Break India’s Digital Language Barrier

COIL-D under BHASHINI is enabling seamless multilingual AI communication across India.

Read full news →

A common repository of Indian Language Data for the promotion and creation of language resources for the Human Language Technology

Under BHASHINI, Funded by MeitY, Govt. of India

COIL-D Visual

About Us

The Mission Bhashini, an initiative by the Ministry of Electronics and Information Technology (MeitY), Government of India, has recently recognized and funded the establishment of the "COIL-D: Centre of Indian Language Data." This esteemed project is being led by Prof. Asif Ekbal, Associate Professor at IIT Patna, in collaboration with IIT Delhi, IIIT Delhi, IIT Guwahati, IGDTUW, MIT Manipal, and DIBD.


Project
Process

Aims

Create language resources like parallel corpora for MT between Indian languages, as well as benchmark datasets for PoS tagging, NER, ASR, and TTS

Primary Focus

Curate core Hindi data from science, healthcare, agriculture, climate, tourism, judiciary, education, governance & conversational content

Key Focus

To create, preserve, and standardize language resources to support NLP research and applications


Applications

This dataset will power Hindi-to-21 language translation and multilingual chatbots, enabling efficient cross-sector communication

Initiative

Establish a central repository for Indian language data and provide a platform for developing and benchmarking HLT applications

Results

With minimal post-editing, you can quickly translate large volumes of text, making it ready for publication on print and digital platforms

Development

Develop leaderboards to evaluate MT, PoS tagging, NER, NLG, sentiment analysis, ASR, and TTS, ensuring systematic NLP assessment

Delivery

From these advanced tools at no cost surpassing existing solutions like Google Translate, while also enriching our linguistic heritage

As a data partner, your organization will be acknowledged on the MeitY portal for its valuable contributions to this important national project. Upon completion, due credit will be given for your support, highlighting your role in this significant initiative.


COIL-D Project Objectives

The COIL-D (Centre of Indian Language Data) project aims to establish a unified repository of Indian language data and create a platform for systematic evaluation of Machine Translation (MT) and other Natural Language Processing (NLP) systems. It promotes the creation and preservation of language resources for Human Language Technology (HLT) applications and defines standards for linguistic benchmarking.

Step 1: Identification of Hindi language resources

Identify and list existing Hindi datasets and tools. This helps understand current resource availability.

Step 2: Acquisition of resources across target domains

Collect data from key domains like health, education, and governance. It ensures coverage of real-world language use.

Step 3: Creation of language resources and benchmarks

Develop new data for Machine Translation and NLP. Set benchmarks to evaluate tool performance.

Step 4: Development of MT evaluation leaderboards

Create leaderboards to assess translation systems. They help track progress and encourage improvements.

Step 5: Leaderboards for ASR and TTS technologies

Develop scoreboards to evaluate speech recognition and synthesis systems. These track accuracy, clarity, and performance.

Step 6: Benchmarks for PoS and NER taggers

Define evaluation tests for tools like PoS and NER taggers. This ensures fair and consistent evaluation.

Motivation

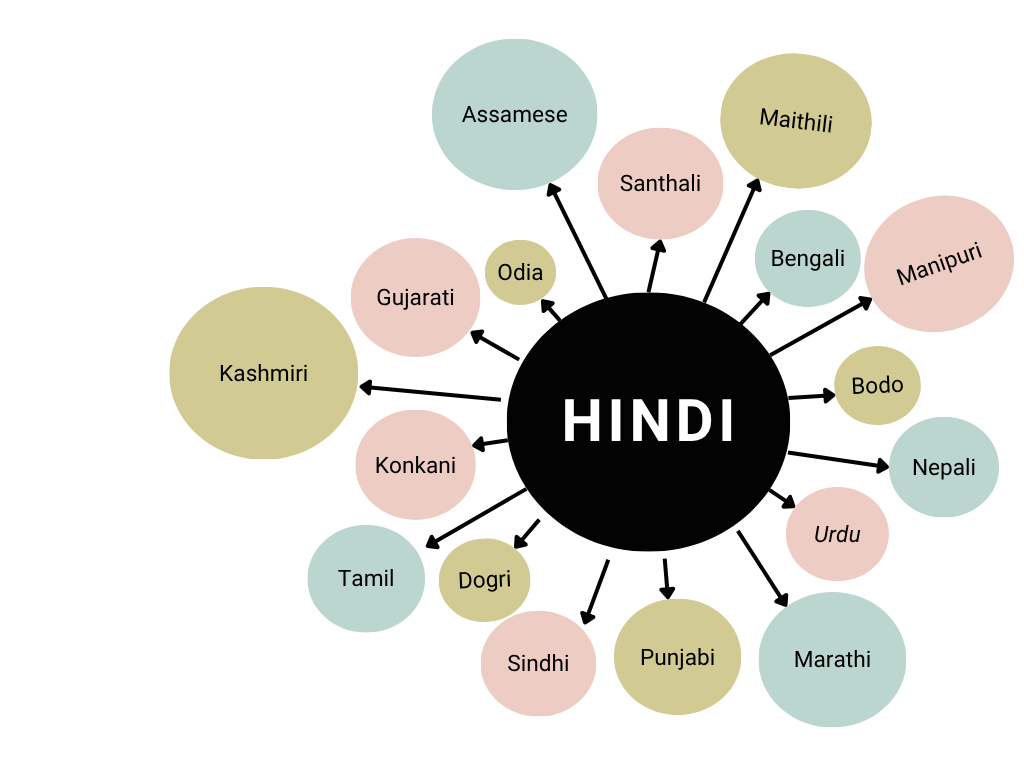
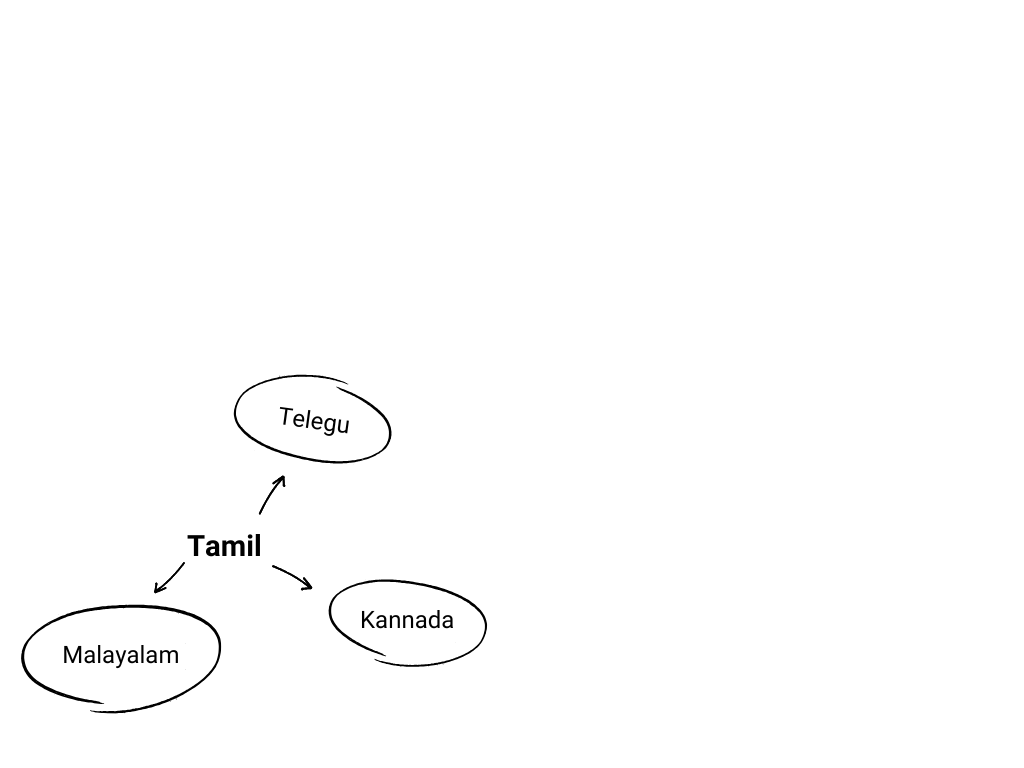
The primary motivation behind gathering Hindi language data is to facilitate translation into 17 other Indian languages. Additionally, we are focusing on Tamil-to-Dravidian language translations.

A significant emphasis is placed on the creation of high-quality language resources. Efforts will be made to generate parallel corpora, aiming for 50k–100k sentence pairs for each language pair, with 2k additional sentence pairs for evaluation purposes. Hindi will serve as a central language, enabling efficient translation between Hindi and other Indian languages. Furthermore, the creation of leaderboards for MT, ASR, and TTS will provide standardized platforms for performance benchmarking. We will also establish benchmarks for various linguistic tools, such as PoS taggers, Named Entity Recognition (NER) systems, Natural Language Generation (NLG), and Sentiment Analysis tools, which will enhance resources available for Indian languages.

Corpora


Machine Translation (MT)
Machine Translation
Machine Translation (MT) is the automatic conversion of text from one language to another using computer algorithms. It enables fast, large-scale translation without human intervention. Modern MT systems often use AI and deep learning to improve accuracy and fluency.
Natural Language Generation (NLG)
Natural Language Generation
Natural Language Generation (NLG) is a branch of AI that automatically produces human-like text from structured data or input. It helps systems write summaries, reports, or responses in natural language. NLG is widely used in chatbots, content creation, and data-driven reporting.
Part-of-Speech (PoS) Tagging
PoS Tagging
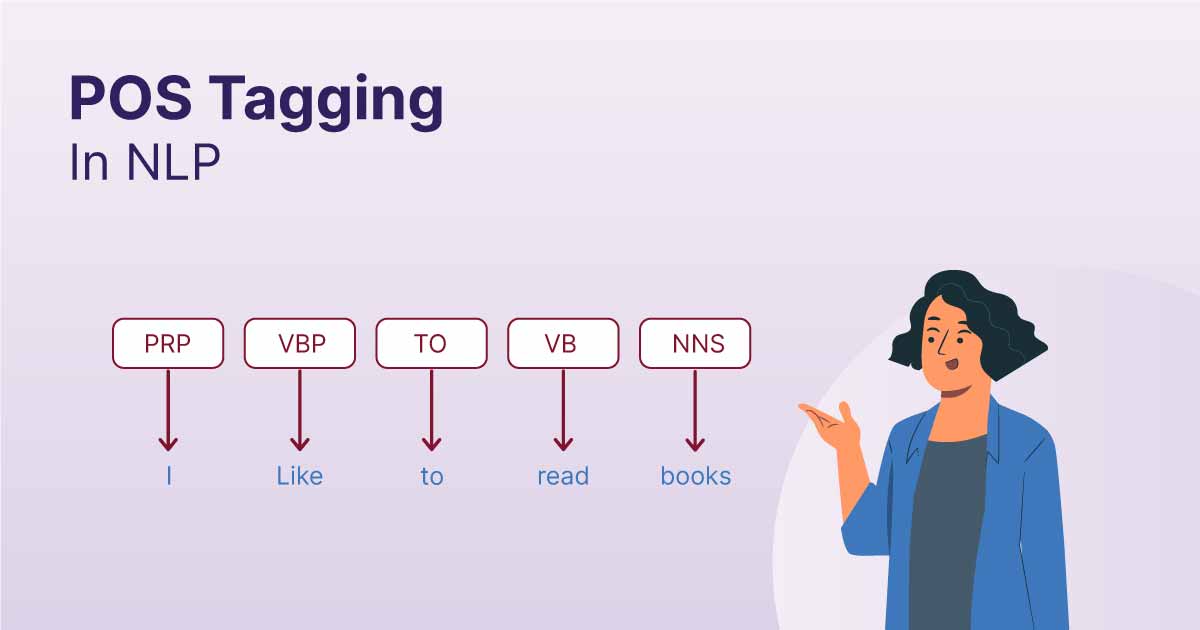
Part-of-Speech (PoS) tagging is the process of labeling each word in a sentence with its grammatical category, such as noun, verb, adjective, etc. It helps machines understand sentence structure and is a key step in many NLP tasks like parsing and information extraction.
Named Entity Recognition (NER)
Named Entity Recognition
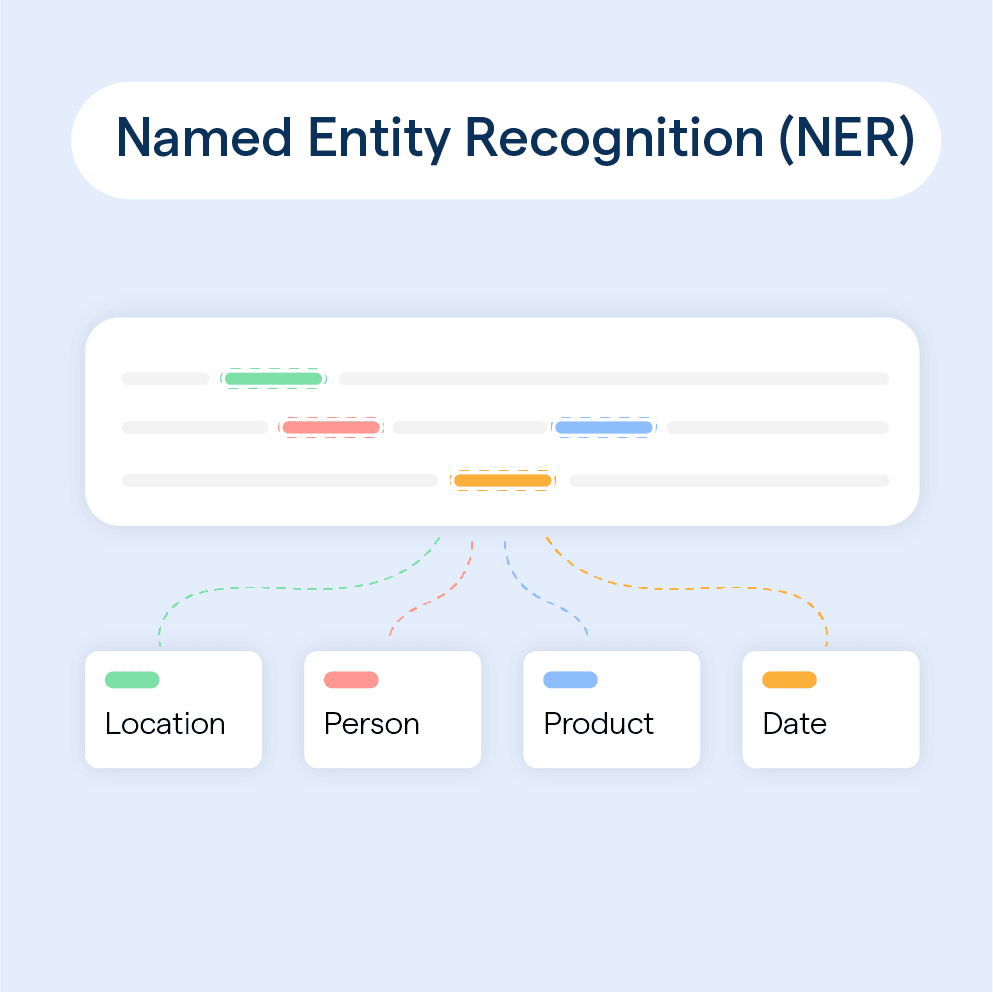
Named Entity Recognition (NER) is a natural language processing technique used to identify and classify entities like names of people, organizations, locations, dates, and more in text. It helps in extracting structured information from unstructured data, enabling better understanding and analysis of content.
Automatic Speech Recognition (ASR)
Automatic Speech Recognition
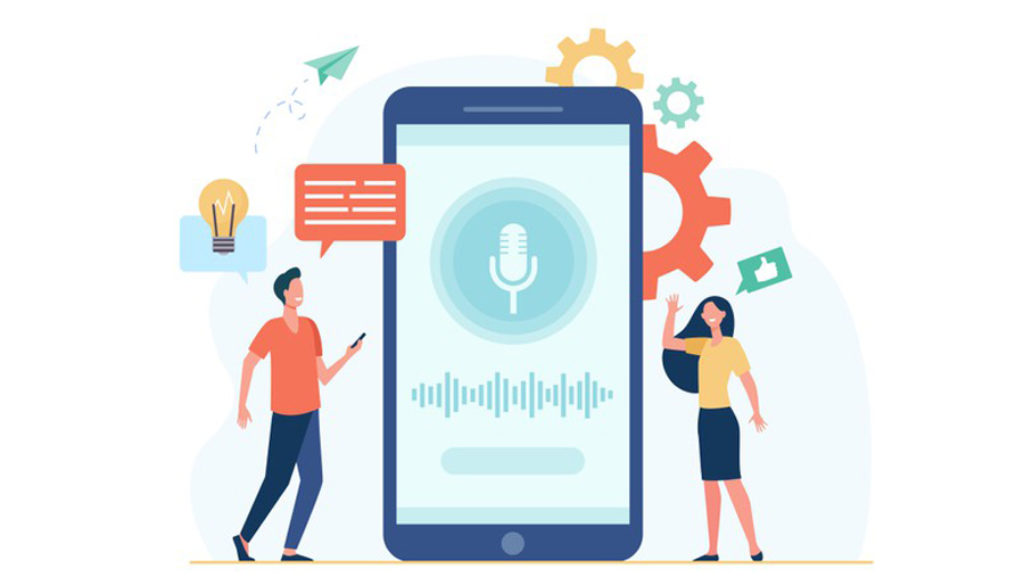
Automatic Speech Recognition (ASR) is a technology that converts spoken language into written text. It enables voice-based interaction with devices and is used in applications like virtual assistants, transcription services, and voice commands.
Text-to-Speech (TTS)
Text-to-Speech
Text-to-Speech (TTS) is a technology that converts written text into spoken voice output. It allows computers and devices to "read aloud" text, making digital content accessible to users, especially in assistive and multilingual applications.

Leader Board

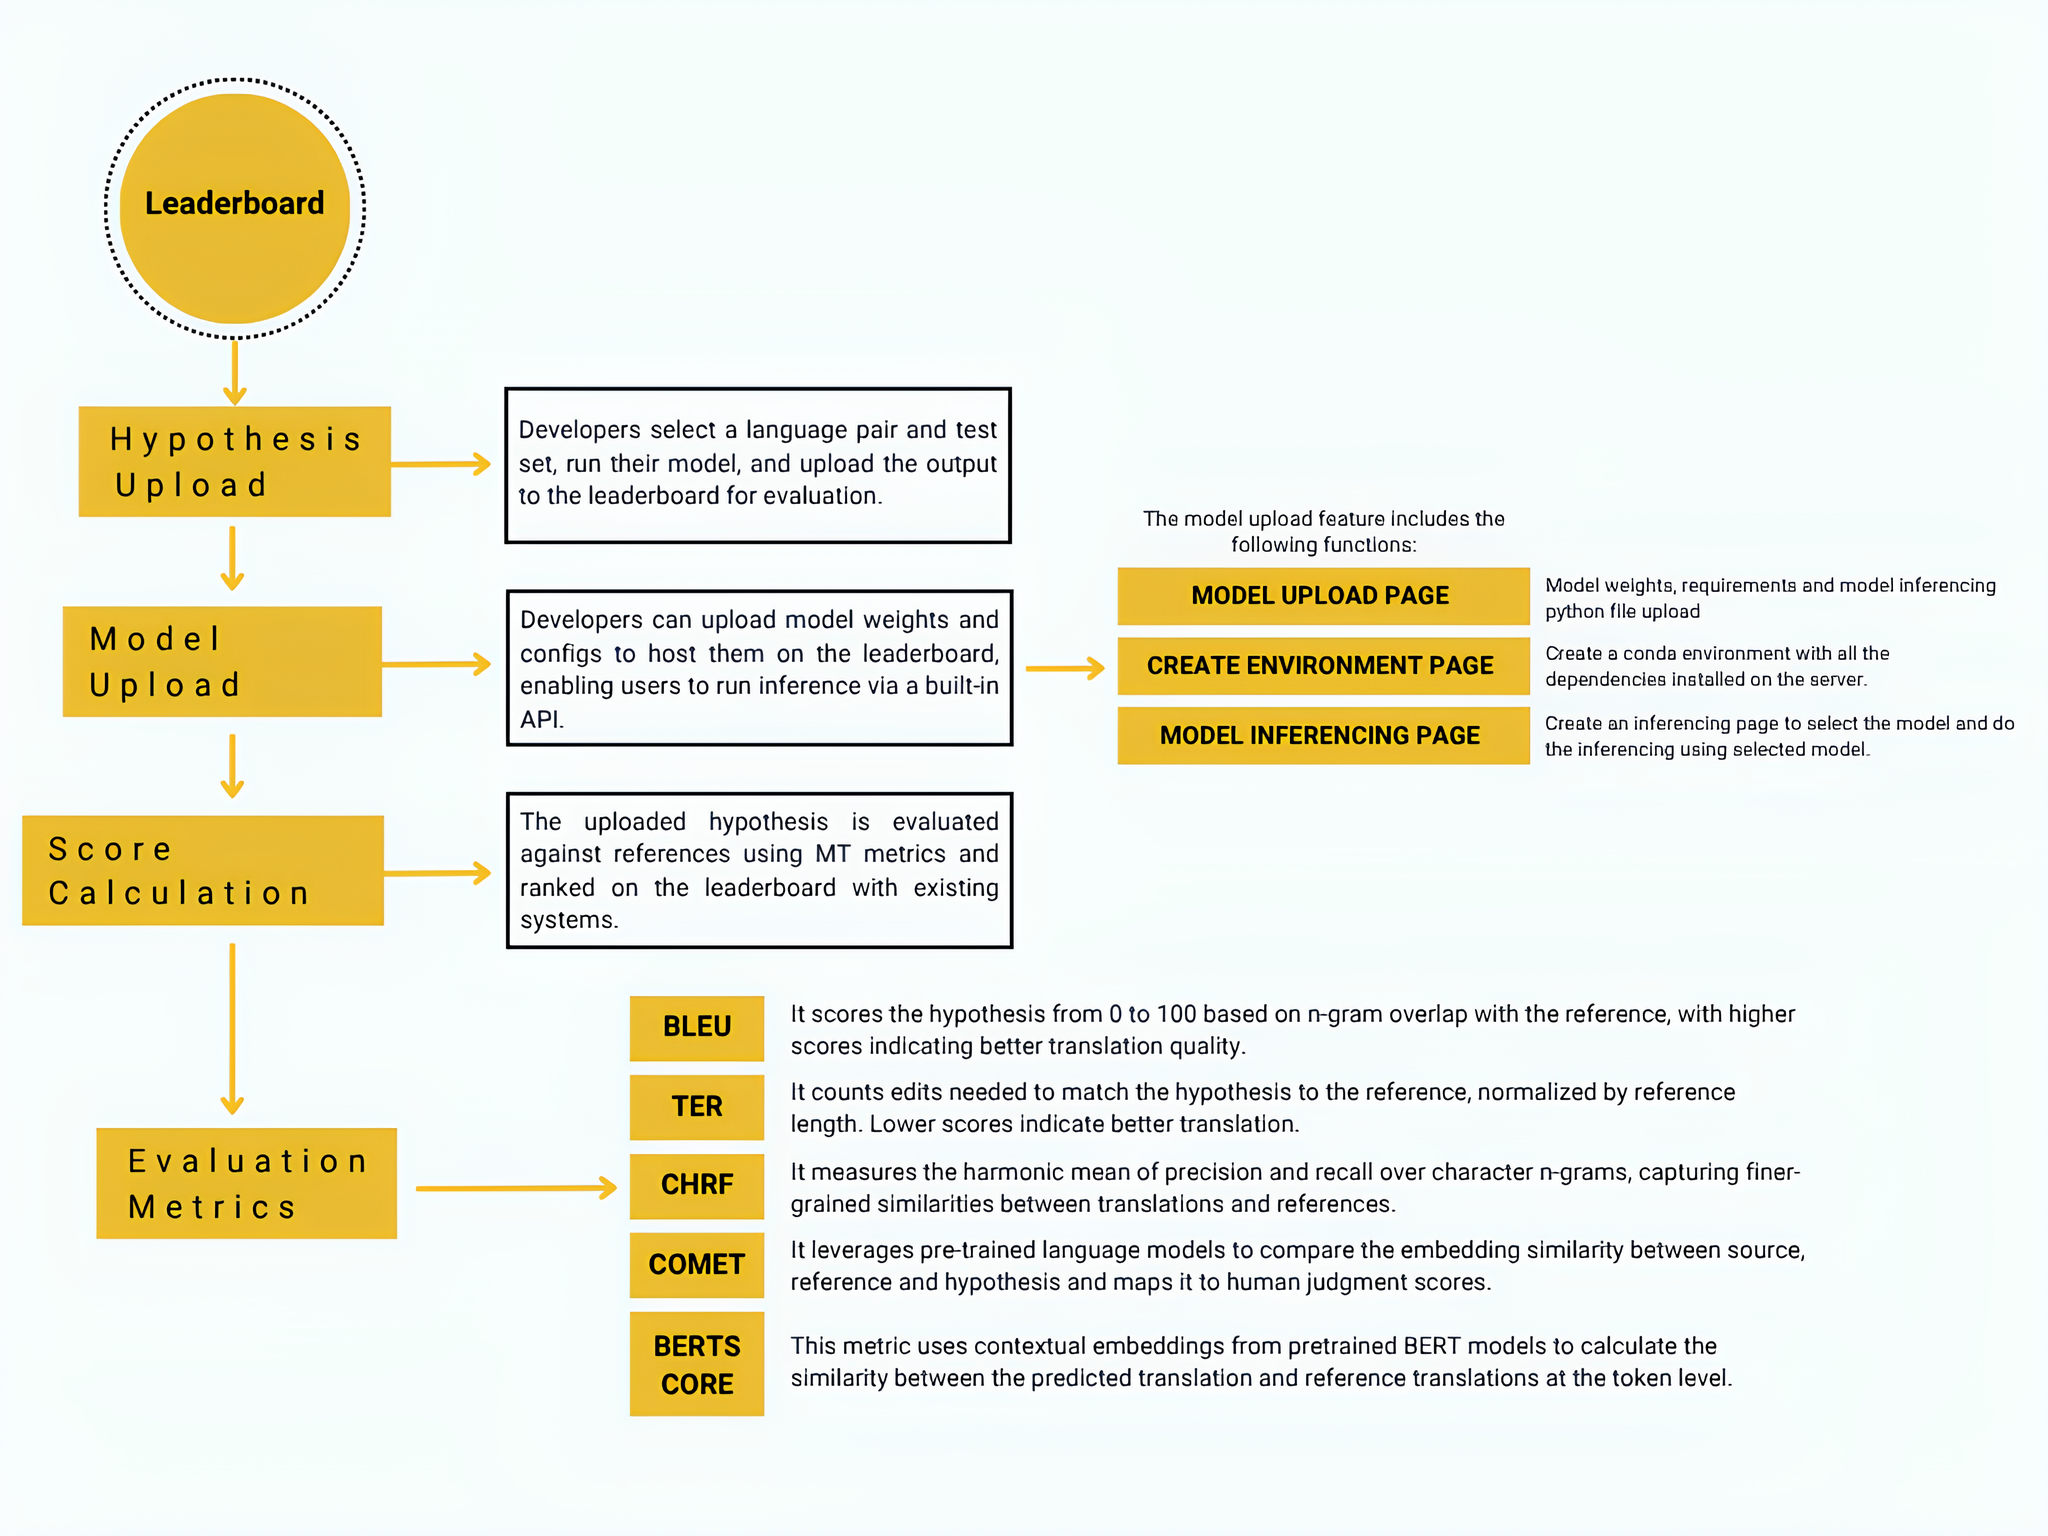
A leaderboard is a platform or framework used to benchmark and compare the performance of different models and algorithms on specific natural language processing tasks. In this case, the leaderboard compares the performance of Machine Translation systems for Indian Languages. The users of this system can be classified broadly into admin, developers and viewers. The admin side will maintain the leaderboard, updating it with new benchmarking datsets, adding newer tasks and other features to the existing framework. The developers are users who would want to compare their MT hypothesis again state of the art model hypothesis. Lastly, the viewers are the visitors to the website.

Consortium Members

Asif Ekbal
Dr. Asif Ekbal

Principal Investigator

Associate Professor
Computer Science and Engineering
IIT Patna, India

Ashwini Vaidya
Dr. Ashwini Vaidya
 

Assistant Professor
HSS
IIT Delhi, India

Tanmoy Chakraborty
Dr. Tanmoy Chakraborty
 

Associate Professor
Electrical Engineering
IIT Delhi, India

Samit Bhattacharyya
Dr. Samit Bhattacharyya
 

Associate Professor
Computer Science and Engineering
IIT Guwahati, India

Sanasam Ranbir Singh
Dr. Sanasam Ranbir Singh
 

Professor
Computer Science and Engineering
IIT Guwahati, India

Shad Akhtar
Dr. Shad Akhtar
 

Assistant Professor
Computer Science and Engineering
IIIT Delhi, India

Poonam Bansal
Dr. Poonam Bansal
 

Professor
AI & Data Science
IGDTUW, India

Amita Dev
Dr. Amita Dev
 

Vice-Chancellor

IGDTUW, India

Muralikrishna
Dr. Muralikrishna S N
 

Assistant Professor (Senior)

Manipal Institute of Technology, MAHE
Manipal, India

Our Collaborators


NCERT Logo

NCERT

Domain: Education

Corpora Mode: Text
AIR Logo

All India Radio

Domain: Media & Broadcast

Corpora Mode: Speech & Text
Free Tamil Books Logo

Free Tamil Books

Domain: Various

Corpora Mode: Text
Skyfox Publishers Logo

Integrated Good Agricultural Practices in Seedless Grapes

Domain: Agriculture

Corpora Mode: Text
Tamil Digital Logo

Tamil Nationalized and Public Domain Books Collection

Domain: Various

Corpora Mode: Text (Public domain)
Press Information Bureau Logo

Press Information Bureau

Domain: Various


Corpora Mode: Text
Dr. Suneel Krishnan Logo

Blog: Dr. Suneel Krishnan

Domain: Various


Corpora Mode: Text
Venkatesh Jambulingam Logo

Educational Blog: Venkatesh Jambulingam

Domain: Science & Technology

Corpora Mode: Text
Shanlax International Journal Logo

Shanlax International Journal of Tamil Research

Domain: Various

Corpora Mode: Text
Social Welfare Dept Logo

Social Welfare and Women
Empowerment Dept.

Domain: Various

Corpora Mode: Text
Roaming Owls Logo

Roaming Owls (Blog)

Domain: Tourism

Corpora Mode: Text
Madras High Court Logo

Madras High Court

Domain: Judiciary

Corpora Mode: Text
PM India Logo

PM India

Domain: Governance & Policies

Corpora Mode: Text
Priyaafilms247 Logo

Youtube channel priyaafilms247

Domain: Various

Corpora Mode: Audio
Pranam Paryatan Logo

प्रणाम पर्यटन magazine

Domain: Tourism

Corpora Mode: Text
NIMHANS Logo

NIMHANS, Bangalore

Domain: Healthcare

Corpora Mode: Text
Vigyan Prakash Logo

विज्ञानं प्रकाश

Domain: Science & Technology

Corpora Mode: Text
Vigyan Garima Sindhu Logo

Vigyan Garima Sindhu

Domain: Science & Technology

Corpora Mode: Text
Prakriti Darshan Logo

Prakriti Darshan

Domain: Climate

Corpora Mode: Text
Geography and You Logo

Geography and You

Domain: Climate

Corpora Mode: Text
Down to Earth Logo

Down to Earth

Domain: Climate

Corpora Mode: Text
Union Budget Logo

Union Budget

Domain: Governance & Policies

Corpora Mode: Text
UP Budget Logo

UP Budget

Domain: Governance & Policies

Corpora Mode: Text
Loksabha Speeches Logo

Loksabha speeches

Domain: Governance & Policies

Corpora Mode: Text
Ministry of Education Logo

Ministry of Education

Domain: Governance & Policies

Corpora Mode: Text
Kanoon Jagat Logo

Kanoon Jagat

Domain: Judiciary

Corpora Mode: Video
Kanoon Jagat Logo

@PleaseSitDown

Domain: Education

Corpora Mode: Video
Indian Meteorological Department Logo

Indian Meteorological Department

Domain: Climate

Corpora Mode: Text
Bihar Tourism Department Logo

Bihar Tourism Department

Domain: Tourism

Corpora Mode: Text & Speech

Stakeholder Engagement

Expression of Interest for language data creation under the COIL-D initiative.

Inviting Startups, Technology Firms, and Language Data Service Providers!

The Indian Institute of Technology Patna (IIT Patna) invites Expressions of Interest (EOI) from eligible startups, technology firms, and specialized service providers for language data creation under COIL-D: Centre of Indian Language Data, a project under the flagship BHASHINI Mission, Ministry of Electronics and Information Technology (MeitY), Government of India.

The initiative aims to develop large-scale, high-quality multilingual datasets to advance Artificial Intelligence (AI), Natural Language Processing (NLP), and Speech Technologies for Indian languages.

Scope of Work

Interested organizations may apply for one or more of the following workstreams:

  • Source Data Collection & Validation
  • Parallel Corpora Creation & Validation
  • Automatic Speech Recognition (ASR) Data Creation
  • Text-to-Speech (TTS) Data Creation
  • Speech-to-Speech Translation (S2ST) Data Creation
  • Sentiment Analysis Data Collection & Annotation
  • Quality Assurance & Validation
Target Languages
Hindi Maithili Santali Odia Bengali

and other Indian languages, including low-resource and tribal languages.

Target Domains
Education Judiciary Healthcare Science & Technology Tourism Climate & Environment Governance Agriculture

and more.

Who Can Apply?

Registered Indian startups, technology firms, MSMEs, and specialized service providers with relevant experience in language technologies, data collection, annotation, transcription, translation, or speech processing.

Important Details

EOI Issue Date: 24 October 2026   |   Last Date for Submission: 8 November 2026

Submission Email: coild.bhashini@gmail.com

Email Subject: EOI Response — COIL-D Data Services — [Workstream Name] — [Company Name]

Publications

Selected research publications and resources from the COIL-D initiative.

arXiv • 2026

COILD: An Indic-Centric Parallel Corpus and Benchmark for Machine Translation Across Indian Languages

Authors: Kshetrimayum Boynao Singh, Nitin Kumar Mishra, Palash Pratim Dutta, Atai Waris Khan, Aparna Kaushik, Avinash Kumar, Deeksha, Deepak Kumar, Saroj Kumar Jha, Saloka Sengupta, Anansa Roy, Umalatha Kannoth, Saifulla Samar, Meena Sharma, Manpreet Kaur, Jyoti Sharma, Ashwini Vaidya, Muralikrishna SN, Md Shad Akhtar, Poonam Bansal, Amita Dev, Sanasam Ranbir Singh, Samit Bhattacharya, Tanmoy Chakraborty, and Asif Ekbal.

Year: 2026   |   arXiv: 2609.28826   |   Category: cs.CL

@misc{singh2026coildindiccentricparallelcorpus,
  title={COILD: An Indic-Centric Parallel Corpus and Benchmark for Machine Translation Across Indian Languages},
  author={Kshetrimayum Boynao Singh and Nitin Kumar Mishra and Palash Pratim Dutta and Atai Waris Khan and Aparna Kaushik and Avinash Kumar and Deeksha and Deepak Kumar and Saroj Kumar Jha and Saloka Sengupta and Anansa Roy and Umalatha Kannoth and Saifulla Samar and Meena Sharma and Manpreet Kaur and Jyoti Sharma and Ashwini Vaidya and Muralikrishna SN and Md Shad Akhtar and Poonam Bansal and Amita Dev and Sanasam Ranbir Singh and Samit Bhattacharya and Tanmoy Chakraborty and Asif Ekbal},
  year={2026},
  eprint={2609.28826},
  archivePrefix={arXiv},
  primaryClass={cs.CL},
  url={https://arxiv.org/abs/2609.28826}
}

Career

Temporary positions available on the COIL-D project (sponsored by MeitY). Applicants should send resume (PDF) and required documents to the email provided below.

Program Manager

Posts: 01 • Salary: Rs. 1,50,000/month (with 10% annual increment)
Location: IIT Patna, Bihta, Patna – 801106
Project No. 1155

The AI-NLP-ML Research Group at IIT Patna is looking for a dynamic Program Manager to join our flagship R&D project, COIL-D: Centre of Indian Language Data, funded by Bhashini, MeitY, Government of India.

Minimum Eligibility

  • First-class B.E./B.Tech. from IIT/NIT or an institution of similar repute; and
  • MBA or M.Tech./M.E. with a good track record; and
  • Minimum 3–4 years of relevant work experience; or
  • MBA/M.Tech. from a reputed institution with 3–4 years of experience.

Desirable: Experience in the technology business sector. Prior experience in managing or coordinating projects related to Natural Language Processing (NLP) or Indian language technologies will be an added advantage.

Key Responsibilities

  • Overall management of the project under the Chief Investigator (CI)
  • Coordinating with consortium institutions and MeitY officials
  • Preparing project reports and tracking finances
  • Facilitating meetings and keeping the CI updated
  • Any other responsibilities assigned by the CI

About the Project

COIL-D aims to create large-scale language resources for Indian languages, including:

  • Parallel corpora for Machine Translation (MT)
  • Benchmark datasets for PoS tagging, NER, ASR & TTS
  • NMT model development & LLM evaluation
  • Leaderboards for MT, NER, NLG, Sentiment & TTS tasks

Junior Research Associate – Language (Odia-02)

Posts: 02 • Salary: Rs. 45,000/month (with 10% annual increment)

Minimum Eligibility

  • B.A. (Language or Linguistics) with 2 years of experience in the relevant area; or
  • M.A. (Language or Linguistics) with exposure in the relevant area; or
  • M.Phil./PhD in language or linguistics or in the related discipline.
  • Knowledge in Hindi/Maithili/Odia/Bengali languages

Contact

Address

IIT Patna, Bihta Kanpa Rd, Patna,
Dayalpur Daulatpur, Bihar 801106

Call Us

+91 6115 233 338


Email Us

coild.bhashini@gmail.com